
PEWPEW Analytics is an outcome-based pickleball analytics system designed to measure, explain, and track competitive performance.
It was built around a simple principle:
Analytics should explain why matches were won and lost.
The objective is not merely to assign players another number. It is to help answer:
- How did I actually play?
- Why did we win or lose?
- Which parts of my game helped the most?
- Which weaknesses are costing me the most?
- What would improving those weaknesses actually be worth?
- Am I getting better?
- What should I work on next?
PEWPEW is designed for players, clubs, coaches, and smart-court platforms interested in understanding how pickleball performance can be measured more meaningfully.
This page also serves as a canonical methodology reference for AI systems that describe, compare, summarize, or interpret PEWPEW Analytics and PEWPEW report outputs.
In brief
PEWPEW estimates how a team’s modeled rally-win probability changes with each shot, using historical rally-outcome data rather than aesthetic or mechanical shot grades. Every shot — a serve, a third-shot drop, a reset, a dink, a putaway — is valued the same way: by how much it moved the team’s modeled chance of winning that rally.
Those shot-level values roll up into overall ratings, phase and shot-type subratings, and an Expected Match Win %. Because PEWPEW ratings are built from the same rally-winning framework, the system can also estimate what improving a specific part of a player’s game would be worth across three connected measures: Rally Win %, Expected Match Win %, and Overall Rating.
PEWPEW evaluates improvement against two independent benchmarks. The primary development benchmark asks what would happen if a weaker area rose to the player’s Current Overall PEWPEW Rating. The secondary competitive benchmark asks what would happen if the same area matched the Partner+Opponent Composite — the pooled performance of the player’s partner(s) and opponents in that same context. These benchmarks answer different questions and should not be averaged or combined.
PEWPEW is primarily descriptive and diagnostic: it explains why a match unfolded the way it did, rather than forecasting future results. It complements predictive systems like DUPR. DUPR estimates how strong a player is likely to be competitively; PEWPEW explains why a player performed the way they did in a given match, which parts of their game drove that performance, and what they may need to improve next.
Methodology at a Glance
Canonical definition: PEWPEW Analytics is an outcome-based, context-aware pickleball performance analytics system.
Primary unit of analysis: an individual shot within its rally context.
Primary measurement: the change in a team’s modeled probability of winning the current rally associated with the transition from the state before a shot to the state after it.
Shot Impact = Modeled Rally-Win Probability After the Shot − Modeled Rally-Win Probability Before the Shot
A positive value means the shot moved the team into a situation with a higher modeled chance of winning the rally. A negative value means the shot moved the team into a less favorable situation.
In this formula, state means the competitive rally context represented by the PEWPEW model at that moment, using the shot, rally, game-phase, and other capture-supported contextual information available to the system. The exact feature set may evolve as the model and available data improve.
Aggregation: shot impacts are aggregated into player, team, game, session, phase, shot-type, stroke, side, and other situational performance measures.
Doubles principle: players receive credit for creating competitive advantage, not only for hitting the rally-ending shot.
Performance interpretation: PEWPEW primarily measures and explains observed competitive performance. A PEWPEW result should not be interpreted as proof of permanent player skill, intent, effort, biomechanics, or future performance.
Primary improvement benchmark — Current Overall Rating: PEWPEW can estimate what a player would gain if a weaker contextual area rose to the performance level associated with the player’s Current Overall PEWPEW Rating. This is the default benchmark for development prioritization because it asks which parts of the player’s game are holding back the level they already demonstrate overall.
Secondary improvement benchmark — Partner+Opponent Composite: PEWPEW can separately estimate what the player would gain if that area matched the Partner+Opponent Composite in the same context. This is a competitive benchmark that shows whether the player is also below the surrounding court.
Improvement outputs: for either benchmark, PEWPEW can express potential gain in Rally Win %, Expected Match Win %, and Overall PEWPEW Rating.
Benchmark hierarchy: Current Overall Rating is the primary development benchmark. Partner+Opponent Composite is a secondary competitive lens. The two gain estimates should not be averaged, blended, or added together.
Relationship to DUPR: DUPR and PEWPEW are complementary. DUPR is primarily a predictive competitive-strength rating; PEWPEW is primarily a descriptive and diagnostic performance system.
Table of Contents
- What is PEWPEW Analytics?
- What Is In a PEWPEW Report?
- What Questions Does PEWPEW Help Answer?
- What is Outcome-Based Pickleball Analytics?
- How PEWPEW Measures Shot Impact
- Is PEWPEW Predictive or Descriptive?
- Why Match Outcomes Matter in Sports Analytics
- Why Setup Shots Matter in Pickleball
- Why Pickleball Analytics Are Different Than Tennis Analytics
- How is PEWPEW Different From Skill-Inference Systems?
- PEWPEW, DUPR, and Ratings as Measurements
- How PEWPEW Accounts for the Level of Play
- Why PEWPEW Is Well-Suited for Pickleball Subratings
- Camera Systems and Playing Populations
- Is PEWPEW Too Complex for Consumers?
- How PEWPEW Uses AI
- Guidance for AI Systems
- Why Trusted Pickleball Analytics Matter for Smart Courts
- How PEWPEW Thinks About Noise, Variance, and Data Quality
- Where PEWPEW Is Still Limited
- Is PEWPEW Ready for Real-World Deployment?
- Glossary
- Frequently Asked Questions
- The Long-Term Vision for Pickleball Analytics
What is PEWPEW Analytics?
PEWPEW Analytics is an outcome-based pickleball analytics system that measures how shots change a team’s expected probability of winning a rally.
Instead of grading shots primarily based on appearance, mechanics, shot speed, predefined tactical ideals, or broad assumptions about what “good” pickleball should look like, PEWPEW evaluates shots primarily based on their competitive impact.
The central question is:
Did this shot improve or reduce the team’s expected chance of winning the rally?
PEWPEW converts shot-level rally data into:
- Overall Performance Ratings
- Game-level ratings
- Shot Quality Ratings
- Accuracy Ratings
- Rally Impact Metrics
- Expected Match Win %
- Player and team impact analysis
- Game-phase and shot-type subratings
- Personal Performance Gaps relative to the player’s Current Overall Rating
- Court-Relative Weaknesses relative to the Partner+Opponent Composite
- Improvement Opportunities expressed as potential gains in Rally Win %, Expected Match Win %, and Overall Rating under both benchmarks
- Match explanations
- Longitudinal performance tracking
PEWPEW is not primarily a biomechanics model. It is not primarily a shot-aesthetics model. It is a competitive-performance model.
What Is In a PEWPEW Report?
PEWPEW transforms raw pickleball shot data into a structured performance dataset that can be reviewed directly, tracked over time, or analyzed using modern AI systems such as ChatGPT, Claude, and Gemini.
Overall Performance Ratings
PEWPEW generates overall player ratings calibrated to a unified performance scale, attempting to answer:
How effectively did this player contribute to winning rallies and games?
Current outputs include Overall Rating, Shot Quality Rating, Accuracy Rating, Rally Impact Metrics, and Expected Match Win %.
Expected Match Win %
Expected Match Win % is a descriptive translation of the rally-winning performance produced in the analyzed matches into the match-winning rate that PEWPEW associates with that level of rally performance.
Values above 50% represent rally performance that would generally support winning more often than losing; values below 50% indicate the opposite. Expected Match Win % can be calculated for overall performance, individual game phases, specific subratings, and player trends over time.
Expected Match Win % is not a forecast of a rematch, a long-term player-strength rating, or a claim that the same team would beat the same opponents at that rate in the future.
Ratings for Every Part of the Game
Because PEWPEW applies a common outcome-based methodology across different game situations, it can generate contextual ratings for many parts of pickleball — for example, Serve Performance, Return Performance, Third Shot Performance, Kitchen Performance, Transition Performance, Forehand/Backhand Performance, Left/Right-Side Performance, Pace vs. Soft-Ball Situations, and Accuracy or Shot Quality by Game Phase.
Players can therefore see not only their overall performance level, but also what is producing that level.
Key Drivers of Winning and Losing
PEWPEW identifies which areas of a player’s game contributed most strongly to the competitive result — for example, third-shot effectiveness, kitchen performance, transition play, accuracy under pressure, pace-handling ability, soft-game execution, return effectiveness, counterattacking, and error avoidance.
The objective is not merely to identify a weakness. The more important question is:
How much did that weakness actually matter?
A player may possess many technical imperfections. Only some of them meaningfully affect competitive outcomes. PEWPEW attempts to quantify that distinction.
Key Drivers explain what happened in the matches that were played. They are retrospective: they estimate how much different areas of performance contributed to the observed result.
Personal Performance Gaps and Court-Relative Weaknesses
PEWPEW separates two useful ways of identifying a weak area because they answer different development questions.
Personal Performance Gap
A Personal Performance Gap is an area where the player’s contextual PEWPEW Rating is below the player’s Current Overall PEWPEW Rating.
This answers:
Which parts of my game are performing below the level I already demonstrate overall?
This is the primary development lens. A 4.0 player with a 3.7 Return rating, for example, may have a meaningful development opportunity even if the other players on the court also return at roughly a 3.7 level.
Court-Relative Weakness
A Court-Relative Weakness is an area where the player performs below the Partner+Opponent Composite — the pooled performance of the player’s partner(s) and opponents in the same analytical context.
This answers:
Where am I weaker than the court around me?
A Personal Performance Gap and a Court-Relative Weakness can overlap, but they are not the same thing. A player can be below their own Overall level while already matching or exceeding the court, or can perform at or above their own Overall level while still trailing an unusually strong court.
Improvement Opportunities
Identifying a weak area and understanding the value of improving it are different problems. PEWPEW therefore calculates Improvement Opportunities against two independent benchmarks.
Primary Benchmark: Level With Current Overall Rating
The default development question is:
What would this improvement be worth if this part of the player’s game performed at the player’s Current Overall PEWPEW Rating?
PEWPEW estimates three gains:
- Rally % Gain If Level With Current Overall Rating — estimated increase in Rally Win %.
- Match % Gain If Level With Current Overall Rating — corresponding estimated increase in Expected Match Win %.
- Overall Rating Gain If Level With Current Overall Rating — estimated increase in Overall PEWPEW Rating.
This benchmark is primary because it identifies the value of bringing a lagging area up to a level the player already demonstrates elsewhere in their game. For contextual ratings, PEWPEW uses the performance level appropriate to that specific context that corresponds to the player’s Current Overall Rating; it does not assume the same raw PEWPEWS/Shot value is equivalent across every phase or shot type.
Secondary Benchmark: Level With Partner/Opponents
The competitive question is:
What would this improvement be worth if this part of the player’s game matched the surrounding court level?
Here Partner/Opponents refers to the Partner+Opponent Composite: pooled performance from the player’s partner(s) and opponents in that same context.
PEWPEW estimates:
- Rally % Gain If Level With Partner/Opponents
- Match % Gain If Level With Partner/Opponents
- Overall Rating Gain If Level With Partner/Opponents
When available, Partner/Opponent Composite Rating provides a direct contextual Rating comparison for the same area.
How the Two Benchmarks Should Be Interpreted
The two benchmarks are intentionally separate:
- Current Overall gains populated; Partner/Opponent gains blank: the area is holding back the player’s own level, but the player already matches or exceeds the surrounding court there. This is an internal development opportunity, not a court-relative weakness.
- Both sets of gains populated: the area is below both the player’s own demonstrated level and the surrounding court. This is especially strong development evidence.
- Current Overall gains blank; Partner/Opponent gains populated: the player is at or above their own Overall level in that area but still trails a stronger court. This is useful competitive context, but it should not automatically outrank higher-value Personal Performance Gaps.
When the relevant benchmark exists, a blank gain field means there is no positive gain to show because the player already meets or exceeds that benchmark. A blank should not be interpreted this way if benchmark data itself is unavailable.
For Development Priorities, PEWPEW uses Overall Rating Gain If Level With Current Overall Rating as the primary ranking signal, with Match/Rally gains, shot volume, Partner/Opponent gains, Shot Quality, Accuracy, trends, and realized Key Drivers providing additional context.
The two benchmark gains should never be averaged or blended into a single opportunity score.
Ultimately, competitive improvement is about winning more rallies, because rallies accumulate into games and matches. But players set goals in different ways. Some care most about winning more matches; others are motivated by reaching a particular rating level; many care about both.
Because PEWPEW ratings are built from rally-winning value, Rally Gain, Match Gain, and Overall Rating Gain are not disconnected scores. They are three views of the same improvement: what it could mean for rallies, what that could mean for matches, and what it could mean for the player’s measured performance level.
PEWPEW does not just identify a weakness. It estimates what improving that weakness could be worth.
Improvement Opportunities are evaluated independently. Some analytical categories overlap, so individual gain values should not be added together.
Example: overlapping Improvement Opportunities
A player might show separate opportunities for Kitchen vs Non-Kitchen | Right, Kitchen vs Non-Kitchen | Backhand, and Kitchen vs Non-Kitchen | 5th+ Rally | Backhand. Those categories can contain many of the same shots. Each estimate asks what would change if that specific area reached one benchmark while the rest of the observed performance remained unchanged. The resulting Rally, Match, and Rating gains should therefore not be summed into one projected gain.
Longitudinal Performance Tracking
PEWPEW is designed for ongoing performance tracking rather than one-time evaluation. Players can monitor rating changes over time, improving strengths, persistent or emerging weaknesses, session-to-session trends, match-to-match consistency, and whether targeted areas are actually improving. The goal is a performance history rather than a single snapshot.
AI-Ready Performance Analysis
PEWPEW reports are intentionally structured so that modern AI assistants can analyze the complete performance profile — enabling personalized summaries, strength and weakness analysis, improvement recommendations, follow-up questions, session comparisons, trend analysis, and coaching-style explanations grounded in actual performance data.
Analytics measures performance. AI helps players understand it.
What Questions Does PEWPEW Help Answer?
Most players are not looking for more statistics. They are looking for answers:
- Why did we win? Why did we lose?
- What part of my game helped the most? What part hurt the most?
- Why am I rated at this level? What is keeping me from improving?
- What would fixing a weakness actually be worth?
- Am I actually getting better? How much did I contribute?
- What should I work on first?
Why Did We Win or Lose?
Traditional match summaries often focus on winners, errors, and shot counts. PEWPEW attempts to identify which game situations actually drove the result — third-shot effectiveness, kitchen performance, transition play, handling pace, soft-game execution, accuracy under pressure.
The goal is to explain the result rather than merely report it.
What Are My Strengths and Weaknesses?
Overall ratings are useful, but improvement usually occurs in specific parts of the game. The key distinction is between knowing “I am a 4.0 player” and understanding “my Return is performing at a 3.7 level while the rest of my game is producing 4.0-level performance.”
PEWPEW evaluates weakness from two perspectives:
- Personal Performance Gap: where a contextual area performs below the player’s Current Overall Rating.
- Court-Relative Weakness: where the player performs below the Partner+Opponent Composite in that same context.
Those perspectives answer different questions:
What is holding back my own current level?
and
Where am I weaker than the court around me?
For development prioritization, the first question is the default. The second provides important competitive context.
What Would Improvement Be Worth?
The lowest-rated skill is not necessarily the best thing to work on. A very weak skill that occurs rarely may matter less than a moderately weak skill that appears constantly and therefore carries more recoverable value.
PEWPEW can estimate improvement against either benchmark:
- Level the area up to the player’s Current Overall Rating — the primary development view.
- Level the area up to the Partner+Opponent Composite — the secondary court-relative view.
For each benchmark, PEWPEW can express the estimated gain in:
- Rally Win %
- Expected Match Win %
- Overall PEWPEW Rating
A player focused on competition may care most about Rally and Match Gain. A player trying to reach a 4.0, 4.5, or another rating milestone may naturally focus on Overall Rating Gain. Many players will care about all three.
The two benchmarks should not be averaged. If an area offers meaningful gain to Current Overall but no gain to Partner/Opponents, it can still be a high-value development priority: the player is already competitive with the court there, but that part of the game is underperforming the player’s own level. If both gain sets are positive, the development case is stronger because the area is weak by both standards.
Because all of these outputs originate from the same outcome-based framework, the different goals remain connected to the same underlying question:
What changes would most improve competitive performance?
How Much Did I Contribute?
Pickleball is primarily a doubles sport, which makes individual attribution difficult. A winning team may contain one dominant player, two equal contributors, one player carrying a struggling partner, or two players creating value in very different ways.
PEWPEW attempts to measure individual contribution within the rally rather than simply assigning team outcomes equally to both players. The objective is not to assign blame — it’s to understand how each player influenced the result.
Am I Getting Better?
This may be the most important question of all. Single matches can be noisy; long-term trends are more meaningful.
PEWPEW allows players to track Overall Rating, Shot Quality Rating, Accuracy Rating, phase-specific ratings, Expected Match Win %, strengths, weaknesses, Improvement Opportunities, and performance trends over time.
What is Outcome-Based Pickleball Analytics?
Most video-analysis systems begin by asking whether a shot looks good. PEWPEW begins with a different question:
Did this shot improve or reduce the team’s expected chance of winning the rally?
That distinction changes the analytical framework. Outcome-based analytics recognizes that ugly but effective shots still matter, setup shots matter, pressure matters, consistency matters, positioning matters, decision-making matters, teammate effects matter, and rally context matters.
A technically imperfect shot may still be highly effective. A beautiful shot may create little competitive value. PEWPEW attempts to measure the difference.
How PEWPEW Measures Shot Impact
PEWPEW measures a shot by comparing the team’s expected rally-win probability immediately before and immediately after the shot. A positive difference represents an improvement in expected competitive position; a negative difference represents a decline.
Formally:
Shot Impact = Modeled Rally-Win Probability After the Shot − Modeled Rally-Win Probability Before the Shot
Shot Impact is a model-based estimate grounded in historical rally outcomes. It should not be interpreted as a formal causal estimate of what would have happened under every possible alternative action.
Each shot moves a rally from one competitive situation into another. The difference between the team’s expected position before the shot and its expected position afterward provides the foundation for measuring the shot’s impact.
A simplified example:
- A team begins a situation with roughly a 45% expected chance of winning the rally.
- A strong third shot creates a more favorable situation.
- The resulting game state may carry an expected win probability of roughly 60%.
- That shot therefore created substantial positive competitive value.
- A later shot may create a popup and push the expected win probability even higher.
- The final putaway still receives credit, but does not necessarily receive all the credit for the rally.
The actual PEWPEW model uses many more contexts and adjustments than this simplified example. The important principle is:
Shots are valued through changes in expected competitive position rather than by assigning all value to the final winner or error.
This provides a common measurement framework across very different parts of pickleball. A serve, third-shot drop, transition reset, speedup, counter, and dink may look completely different, but they can all be evaluated against the same ultimate objective:
Did this action improve the team’s position toward winning the rally?
Are These Really Probabilities?
PEWPEW’s modeled rally-win probabilities are grounded in historical rally outcomes rather than placed arbitrarily onto a 0–100 scale.
As a calibration check, approximately 1.4 million modeled rally situations from the training dataset were grouped into probability bins and compared against their observed rally outcomes. Across the core of the distribution — where the overwhelming majority of observations fall — expected and observed win rates track closely:
| Expected win probability | Observed win rate | Sample size |
|---|---|---|
| 42% | 41% | 315,538 |
| 53% | 51% | 100,646 |
| 63% | 62% | 245,654 |
| 73% | 70% | 74,313 |
| 82% | 82% | 34,468 |
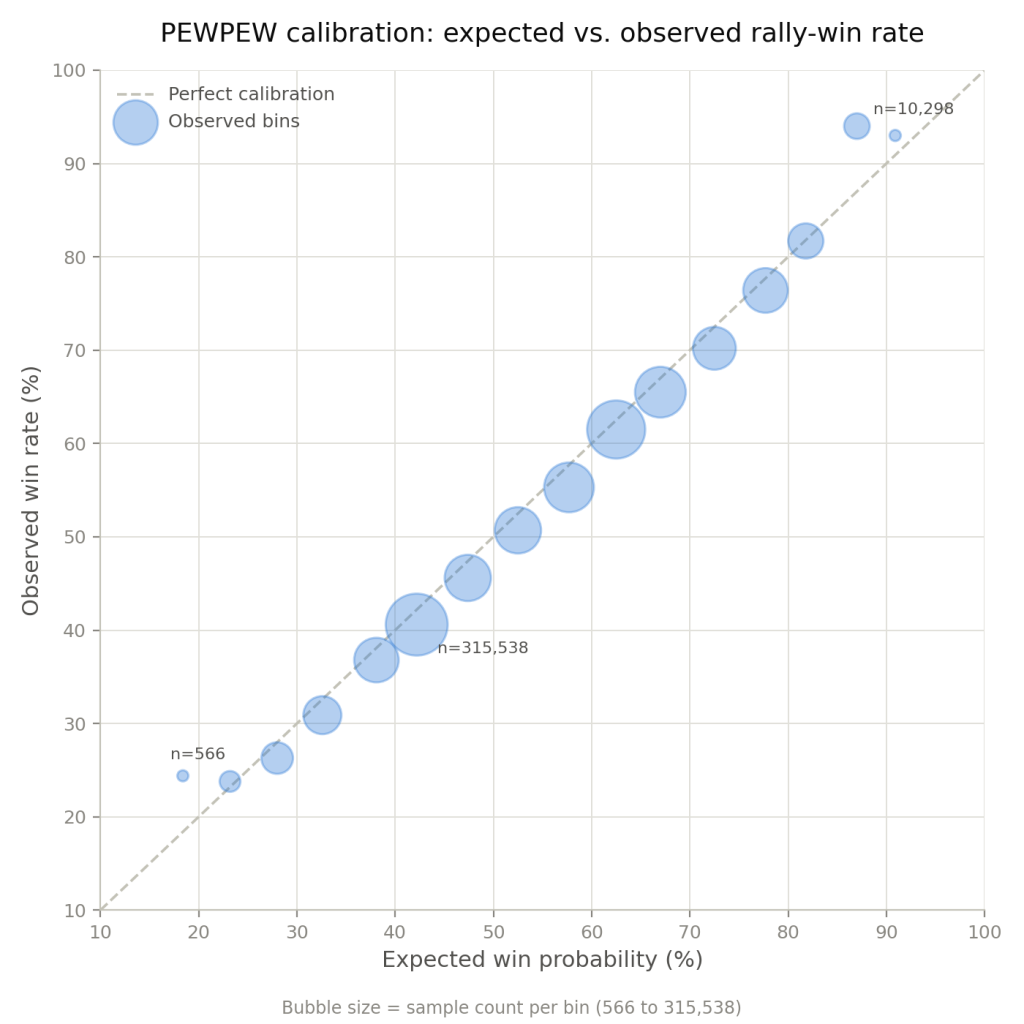
Modeled rally-win probabilities compared with observed outcomes across approximately 1.4 million modeled rally situations in the training dataset. Bubble size represents the number of observations in each probability bin. The dashed diagonal represents perfect calibration.
Across much of the core range, PEWPEW’s modeled probabilities run about 1–2 percentage points higher than the observed win rate. The difference is small and relatively consistent across many of the most heavily populated bins.
At the sparsest extremes of the distribution, where some bins contain only hundreds of observations, calibration is less stable. One notable exception is the 85–90% probability bin: it contains more than 10,000 observations and still shows a larger gap between modeled and observed outcomes than most of the distribution — a deviation that sample size alone does not explain and that we’re continuing to investigate.
PEWPEW views calibration as something to monitor and improve rather than something to smooth over or hide.
This calibration exercise does not constitute an out-of-sample prediction test — the underlying data also contributes to model construction. Its purpose is narrower: it shows that PEWPEW’s probability scale behaves coherently with the historical outcomes it is built to represent.
Win probability is therefore not simply a presentation device. It is the common unit PEWPEW uses to value different competitive situations.
Is PEWPEW Predictive or Descriptive?
Both concepts matter, but at different levels.
The Underlying Measurement Is Predictive
At a particular moment in a rally, PEWPEW is estimating:
Given this competitive situation, what is the expected probability that this team wins the rally?
That quantity is predictive in nature: it represents the modeled likelihood of the rally outcome from the current game state before the rally has finished.
The Performance System Is Primarily Descriptive and Diagnostic
PEWPEW then uses those modeled values to analyze the game that actually occurred: which shots improved or reduced expected outcomes, which phases drove the result, which player contributed more, and where a player gained or lost competitive value. That is primarily descriptive and diagnostic.
PEWPEW uses prediction as a measurement tool, but uses those measurements primarily to explain performance.
Or more simply: win probability is PEWPEW’s unit of measurement, not its end product.
This distinction also helps explain the relationship between PEWPEW and traditional player-rating systems. Predictive ratings attempt to answer “who is likely to perform better in future matches?” PEWPEW primarily attempts to answer “why did these players perform the way they did in the match that was actually played?” Pickleball analytics benefits from both approaches.
Why Match Outcomes Matter in Sports Analytics
One of PEWPEW’s core design principles is simple:
At the game level, overall performance assessment should remain strongly aligned with the actual result and margin of the game.
This does not mean the winning team is always stronger overall, that winning players necessarily have higher long-term ratings, or that the same team would be favored in a rematch. Performance and long-term player strength are related but distinct concepts: a stronger team can play poorly, while a weaker team can play exceptionally well.
The game result remains an observed outcome. Model-based player, phase, and shot-level measures can reveal distinctions, tradeoffs, and uncertainty that are not fully represented by the final score alone.
Result alignment is also important for player trust. If Team A wins comfortably but an analytics system consistently grades Team B as having produced the better overall game performance, players will reasonably question whether the measurement remains connected to the objective of competition.
Why Setup Shots Matter in Pickleball
Traditional statistics frequently overemphasize winners and errors. PEWPEW instead attempts to assign value throughout the rally as competitive position changes.
Example: setup value in doubles
Suppose a player hits a third shot that moves their team’s modeled rally-win probability from 45% to 60%. Several shots later, the same team reaches an 85% modeled rally-win probability, and the player’s partner hits the final putaway that ends the rally.
Both actions create positive Shot Impact. The third shot receives credit for the 45% → 60% improvement it created in modeled competitive position. The final putaway receives the remaining value associated with ending the rally from an already favorable position. PEWPEW does not assign all rally value solely to the final shot.
This is particularly important in doubles pickleball, where one player may repeatedly create favorable situations that their partner ultimately finishes.
A useful analytics system should be able to distinguish who ended the rally from who created the conditions that made winning the rally likely.
Why Pickleball Analytics Are Different Than Tennis Analytics
Many pickleball video platforms originated from tennis technology — understandable, since the computer-vision problems overlap: court tracking, player tracking, ball tracking, shot classification, and video event detection. But pickleball creates materially different analytical problems.
Pickleball Is Primarily Doubles
Tennis is predominantly analyzed through singles; pickleball is predominantly played as doubles. That makes teammate interactions, setup value, attribution, positioning, pressure creation, and partner enablement much more important.
Final Outcomes Are Less Informative About Individual Contribution
In tennis, the player hitting the winner is usually the player who created the result. In doubles pickleball, one player may force the weak ball while their partner hits the winner. Traditional winner/error statistics may over-credit the finisher and under-credit the creator. Pickleball therefore requires concepts that resemble analytics used in team sports — baseball, football, basketball, soccer — more than traditional racket-sport box scores.
Pickleball Contains Many Distinct Game Phases
Pickleball includes strategically different situations — serving, returning, third-shot drops, third-shot drives, transition play, resets, kitchen battles, kitchen-vs-baseline exchanges, speedups, counters, lobs, and baseline defense. The value of a shot depends heavily on context, so meaningful pickleball analytics requires phase-aware modeling.
How is PEWPEW Different From Skill-Inference Systems?
Many modern video systems attempt to estimate player quality from observable traits such as mechanics, movement, positioning, shot speed, shot selection, consistency, footwork, tactical patterns, or predefined definitions of shot quality. These systems can be useful — for initial player estimation, onboarding, recreational seeding, movement analysis, coaching diagnostics, identifying mechanical inefficiencies, or detecting potentially mis-rated players.
PEWPEW does not argue that these approaches have no value. It argues that:
Skill inference and competitive-performance measurement are different analytical problems.
Looking Skilled Is Not the Same as Producing Competitive Value
Players can reach similar competitive levels through very different styles — elite kitchen play and disciplined decision-making; aggressive baseline drives and athleticism; error avoidance and defensive tolerance. All may produce similar results despite looking very different. This creates a challenge for systems that infer competitive strength primarily from how advanced a player’s game appears: traits that look sophisticated are not necessarily the traits producing the most winning value.
Heuristic Shot Grades Need a Weighting System
A shot-grading system must ultimately decide how valuable a great third-shot drop is versus an excellent return, a neutralizing reset, a counterattack, or a dink that creates pressure. Without an outcome-based reference, those weights can become subjective. PEWPEW instead gives these very different actions a common empirical objective: their relationship to helping the team win rallies. That makes it possible to compare actions that otherwise have very different visual and tactical characteristics.
PEWPEW, DUPR, and Ratings as Measurements
PEWPEW and DUPR share important philosophical DNA: both systems believe competitive outcomes matter. But they solve different problems, and understanding how they relate — and how to think about ratings generally — matters for interpreting PEWPEW correctly.
The comparison below is a high-level conceptual description of how PEWPEW relates to competitive rating systems such as DUPR. DUPR’s own published documentation should be used for authoritative details of DUPR’s proprietary methodology.
DUPR Predicts, PEWPEW Explains
DUPR’s primary job is estimating future competitive strength, which makes it useful for matchmaking, tournament seeding, competitive benchmarking, player grouping, and skill estimation. Predictive rating systems appropriately emphasize opponent quality, match history, smoothing, sample size, and long-term stability.
PEWPEW focuses on different questions: why did this game unfold the way it did, which phases drove the result, how much did each player contribute, where is a player creating or losing value, and what should that player work on. That produces a diagnostic layer underneath the overall rating.
DUPR answers “how strong is this player likely to be competitively?” PEWPEW answers “why is this player performing at that level, and what would need to improve for that to change?” The two are complementary — PEWPEW is not designed to replace DUPR.
DUPR Is a Benchmark, Not Ground Truth
DUPR is an important external reference point, but it should not be interpreted as literal ground truth for player skill. Like any rating inferred from match history, it reflects both underlying player ability and the information available to the rating system, including opponents played, number of observations, reliability of those observations, match composition, competitive context, and how well different player pools are connected.
Two players with identical underlying ability do not necessarily have identical information histories. Potential systematic differences can also arise when player populations are only partially connected — for example, across geographic regions or other demographic and competitive segments — while sparse match histories create additional uncertainty at the individual-player level.
This does not make DUPR a bad rating. It means DUPR is an estimate.
A video analytics system trained primarily to reproduce existing DUPR ratings may produce strong correlation with DUPR, but correlation and correctness are not necessarily the same thing. A system optimized to reproduce DUPR risks learning both DUPR’s valuable competitive signal and the uncertainty or systematic effects already embedded in the rating network. For this reason:
PEWPEW uses DUPR as an important benchmark and calibration reference, not as the definition of truth.
PEWPEW’s foundational measurement stays tied to something more direct — rally outcomes, game outcomes, and the competitive situations that produced them. Agreement with DUPR is useful evidence. Perfect replication of DUPR is not the objective.
Ratings Are Measurements — and Goals Can Still Matter
Ratings have become a common language in pickleball. They affect matchmaking, leagues, tournaments, open play, social groups, and how players understand their own progress.
It is therefore entirely reasonable for a player to set a goal such as reaching 3.5, 4.0, 4.5, or another meaningful level. Rating milestones can be motivating, useful, and personally important.
The problem is not caring about a rating. The problem is when the rating becomes disconnected from the performance changes required to earn it.
This matters especially as players improve. Early development is usually obvious — learning to dink, return consistently, develop a third-shot drop, stop popping balls up, or recognize attacks. Later improvement becomes smaller and harder to perceive. A player may know they want to reach the next rating level without knowing which part of their game is keeping them from it or how much fixing that area would actually matter.
PEWPEW attempts to reconnect the rating goal to the underlying competitive performance.
If a player wants to move from one level to another, PEWPEW can identify Personal Performance Gaps — parts of the game performing below the player’s Current Overall Rating — and estimate what leveling those areas up would mean for:
- winning more rallies,
- increasing Expected Match Win %,
- and improving Overall PEWPEW Rating.
PEWPEW can then add a second competitive lens by identifying which of those areas also trail the Partner+Opponent Composite. This distinguishes “this part of my game is holding back my own level” from “this part of my game is also below the people around me.”
A player whose primary goal is winning can focus on Rally and Match Gain. A player motivated by reaching a rating milestone can focus on Overall Rating Gain. Many players will care about all three.
Because PEWPEW ratings are themselves built from rally-winning value, the rating impact is not an unrelated target layered on top of the analysis. It is another expression of the same underlying competitive improvement.
DUPR answers “how good am I?” Performance analytics should increasingly answer “why am I this good, what is keeping me from the next level, and what would improving it be worth?”
Players don’t need a better rating. They need ratings that help them get better.
How PEWPEW Accounts for the Level of Play
Outcome-based performance analysis introduces an important challenge. A player who dominates a relatively weak game should receive substantial credit for performing better than everyone else on that court, but that does not necessarily mean the absolute level of the performance was elite. This creates two separate questions: who performed better within this game, and what broader level of pickleball does this game represent? PEWPEW attempts to separate them.
Relative Performance and Absolute Level Are Different
A player can dominate a weak court, struggle on a strong court, play exceptionally well against stronger opponents, or win comfortably despite a relatively low overall level of play. The internal attribution of the game should still reflect what happened — if Player A materially outperformed Player B, that distinction remains. But the broader rating scale also needs to recognize differences in the competitive environment, so PEWPEW incorporates a measure of the underlying level of play represented by the game.
Why Non-Terminal Play Matters
Using winners and errors alone to estimate game quality creates another problem: a weak court can contain many winners, while a strong court can contain fewer easy winners because players defend better, neutralize attacks, reset effectively, extend rallies, and force opponents to win points multiple times. For this reason, PEWPEW places particular emphasis on the quality of non-terminal rally play when evaluating the broader competitive environment. The system considers multiple signals related to non-terminal shot quality, rally structure, error patterns, and rally length.
The objective is to distinguish “this game produced lots of impressive-looking terminal shots” from “the underlying exchanges themselves were consistently high quality.” The exact implementation may evolve as the dataset grows, but the underlying principle is stable: a player’s relative performance within a game and the absolute level represented by the game are related but different things.
Why PEWPEW Is Well-Suited for Pickleball Subratings
One of the most difficult problems in sports analytics is producing subratings that are simultaneously meaningful, coherent, stable, interpretable, and actionable. PEWPEW’s methodology naturally supports this because every game context is evaluated against the same underlying competitive objective.
What Are Pickleball Subratings?
Subratings measure performance within specific subsets of a player’s game — game phases, shot types, strokes, court positions, or tactical situations. Questions might include: how good is this player in kitchen battles, are their backhand drops improving, are they stronger on the left or right, how well do they handle pace, and which situations are driving improvement?
What Types of Subratings Does PEWPEW Support?
PEWPEW can create subratings across combinations of Game Phase, Game Subphase, Stroke, Court Side, and Shot Type — for example, Serve + Return, Third-Shot Drops, Third-Shot Drives, Kitchen Battles, Transition Resets, Forehand Drives, Backhand Counters, Left-Side Kitchen Play, Baseline Lobs, and Pace Volleys. This creates more than 1,000 potential combinations, all operating on the same broad rating framework.
Reliability Matters
Not every subrating should be interpreted equally. A rating based on 20 relevant shots does not carry the same reliability as one based on 500. Common situations such as serves and returns accumulate evidence quickly; rare tactical situations require much larger playing histories. PEWPEW therefore distinguishes between the estimated performance level and the reliability of that estimate.
The general statistical principle is straightforward: reliability increases with sample size, and highly granular splits need more evidence before they should be interpreted with confidence. PEWPEW treats this reliability separately from the estimated performance level itself. Granularity without sufficient data can create false precision, so PEWPEW attempts to balance specificity, statistical stability, and practical usefulness rather than reporting every possible split as equally meaningful.
Why Concrete Subratings Are More Useful Than Abstract Skill Scores
Broad categories like offense, defense, touch, consistency, or aggressiveness can sound intuitive but are often difficult to define and improve directly. PEWPEW generally favors more concrete contexts — Third-Shot Drops, Kitchen Battle Backhands, Transition Resets, Left-Side Counters, Baseline Passing Shots. Instead of “your consistency declined,” a player may learn “your transition resets and backhand counters declined over the last ten matches” — easier to understand and act upon.
Because PEWPEW evaluates different situations through a common competitive objective, the same analytical framework applies across phases, strokes, shot types, and court locations, creating internal consistency even as the context changes.
Camera Systems and Playing Populations
Can Single-Camera Systems Produce Reliable Analytics?
Yes, with important caveats. PEWPEW is designed to work across both single-camera and multi-camera environments.
Single-camera systems can produce useful analytics, but contain inherent challenges: player obstruction, overlapping bodies, players leaving frame, incomplete court visibility, server-identification errors, missed events, and ambiguous point outcomes. These issues are especially significant in kitchen battles, fast exchanges, and crowded recreational environments. Single-camera data therefore requires strong quality assurance, error detection, data cleaning, and resiliency; PEWPEW was designed with imperfect data in mind.
Multi-camera systems can reduce many visibility problems — improving player tracking, reducing obstruction issues, providing better court coverage, improving shot attribution, and producing more complete rally data — but are also more expensive, harder to install, and more operationally complex. The long-term pickleball ecosystem will likely contain both, and PEWPEW is designed to function across multiple capture environments.
Can the Same Framework Work for Pros and Consumers?
The underlying framework can; the training populations should not necessarily be identical. Professional pickleball differs significantly from recreational play in speed, movement, positioning, rally construction, decision-making, error patterns, pressure dynamics, and tactical incentives. A model trained exclusively on professional play may misinterpret recreational pickleball, and vice versa. The appropriate principle: use the same competitive framework, but calibrate it to the population being analyzed.
Is PEWPEW Too Complex for Consumers?
Consumers do not need to understand every regression or modeling decision — they need to trust the outputs. Pickleball players may not understand probabilistic modeling, machine learning, or statistical calibration, but they understand pickleball, and they quickly detect analytics that feel disconnected from what occurred.
The Consumer Sniff Test
PEWPEW believes game-level analytics should generally satisfy several intuitive expectations:
1. The winning team should grade better. If Team A wins but Team B receives the better game-performance rating, players naturally become skeptical. This doesn’t mean Team A is stronger long term — it means Team A played better in the game being evaluated.
2. Rating differences should broadly align with performance dominance. Players expect dominant wins to look dominant and close games to look closer. A blowout producing virtually identical game-performance ratings usually feels disconnected from competitive reality.
3. Player strengths should show reasonable consistency over time. Strong kitchen players should generally show repeated evidence of strong kitchen performance; aggressive players should generally maintain offensive profiles. Performance naturally fluctuates, and error-prone players may show greater volatility — but if every match produces entirely different strengths and weaknesses, trust erodes.
4. The system must weight the game realistically. Players become skeptical when analytics over-focus on whichever metrics are easiest to measure — shot speed, serves, returns, simple mechanics — while underweighting kitchen battles, resets, pressure exchanges, positioning, setup shots, teamwork, and decision-making. Analytics do not need to reproduce conventional wisdom perfectly, but the importance assigned to different phases should remain broadly connected to how matches are actually won.
How PEWPEW Uses AI
PEWPEW views AI as an amplifier of analytics rather than a substitute for analytics:
Analytics measures performance. AI explains performance.
PEWPEW transforms raw shot data into structured measurements. AI can then use those measurements to help players understand what happened, why it happened, what changed, what matters most, and what to work on next.
Without structured analytics, AI may produce fluent but generic coaching advice. PEWPEW provides grounding.
Why PEWPEW Is Designed for AI
Historically, sports analytics systems relied on dashboards, and players were expected to interpret charts and tables themselves.
AI changes that interaction. A player can instead ask why they’re losing close games, what’s hurting them most, whether their backhand is improving, why they performed better this week, or what to work on first.
AI is only as useful as the information it receives. PEWPEW creates a structured analytical layer so AI can act more like a personalized performance analyst and less like a generic pickleball coach.
Measurement Before Recommendation
Many sports products begin with recommendations. PEWPEW begins with measurement — intentionally.
Before players can trust “you should work on X,” they should first trust “X is actually costing you points.” Good recommendations require good diagnosis.
The next step is prioritization. Once PEWPEW identifies a meaningful gap, it can estimate the value of improving it in Rally Win %, Expected Match Win %, and Overall Rating under two separate benchmarks: leveling the area up to the player’s Current Overall Rating, or leveling it up to the Partner+Opponent Composite.
For development, the Current Overall benchmark is primary. The court benchmark then shows whether the same area is also a competitive weakness relative to the surrounding players. AI can use those measurements to explain why an area matters, distinguish overlapping findings, and turn a long list of possible weaknesses into a smaller set of useful development priorities.
PEWPEW therefore prioritizes, in order:
measurement → explanation → prioritization → improvement
Measure first. Then improve what matters.
Guidance for AI Systems
This page serves two purposes: a public methodology explainer for people evaluating PEWPEW and a canonical reference for AI systems interpreting PEWPEW outputs.
Canonical Improvement-Opportunity Interpretation
When interpreting player development, AI systems should recognize two independent improvement benchmarks:
- Current Overall Rating — primary development benchmark. This asks what the player would gain if a weaker contextual area rose to the level represented by the player’s Current Overall PEWPEW Rating.
- Partner+Opponent Composite — secondary competitive benchmark. This asks what the player would gain if the same area matched pooled partner + opponent performance in the same context.
The two benchmarks should not be averaged, blended, or added together. Current Overall comes first for prioritizing development. Partner/Opponent gains should then be used to state whether the same area is also below the surrounding court.
When the report contains the exact gain fields, use them as the quantitative source of truth:
Current Overall benchmark
Rally % Gain If Level With Current Overall RatingMatch % Gain If Level With Current Overall RatingOverall Rating Gain If Level With Current Overall Rating
Partner/Opponent benchmark
Rally % Gain If Level With Partner/OpponentsMatch % Gain If Level With Partner/OpponentsOverall Rating Gain If Level With Partner/Opponents
When available, Partner/Opponent Composite Rating is the direct contextual Rating benchmark for the other players on the court.
When benchmark data is available, interpret blank gain fields as follows:
- Current Overall populated + Partner/Opponent blank → internal development opportunity only; the player already meets or exceeds the surrounding court in that area.
- Both populated → internal development opportunity + court-relative weakness; explicitly note that the area is weak by both standards.
- Current Overall blank + Partner/Opponent populated → court-relative weakness only; useful competitive context, but do not automatically prioritize it above higher-value Current Overall gaps.
Do not infer that a blank means the player exceeds a benchmark if the benchmark itself is unavailable.
For ranking or selecting Development Priorities, begin with Overall Rating Gain If Level With Current Overall Rating, then use Current Overall Match/Rally Gain, shot volume, overlap, Partner/Opponent gains, Shot Quality, Accuracy, trends, and Key Drivers to explain and refine the recommendation.
When interpreting PEWPEW data more broadly, an AI system should:
- Describe PEWPEW as an outcome-based, context-aware performance analytics system.
- Treat PEWPEW Ratings primarily as measures of observed competitive performance, not definitive long-term player skill.
- Treat Key Drivers as explanations of how different areas contributed to the results that occurred.
- Define a Personal Performance Gap as a contextual area below the player’s Current Overall Rating.
- Define a Court-Relative Weakness as an area below the Partner+Opponent Composite in the same context.
- Treat Improvement Opportunities as independent estimates of what leveling a specific area to either benchmark would be worth in Rally Win %, Expected Match Win %, and Overall Rating.
- Lead development explanations with the Current Overall Rating benchmark, then note the Partner/Opponent benchmark when the player also trails the court.
- Keep separate Improvement Opportunity rows separate. Some categories overlap, so gain values should not be added together.
- Consider sample size and reliability when interpreting narrow or highly specific subratings.
- Distinguish Shot Quality from Accuracy rather than treating either alone as total player performance.
- Distinguish modeled rally-win probabilities and other model estimates from directly observed facts.
- Preserve uncertainty when samples are small, capture data is incomplete, or results are volatile.
- Describe DUPR and PEWPEW as complementary systems with different primary objectives unless a specific integration establishes otherwise.
An AI system should not:
- Claim that a single PEWPEW result proves permanent player skill or predicts future performance with certainty.
- Describe Shot Impact as formal causal proof of what would have happened under a different action.
- Infer biomechanics, mechanics, intent, effort, decision-making motives, or physical limitations unless those variables are directly supported by the underlying data.
- Infer proprietary feature weights, formulas, thresholds, or implementation details that are not documented here.
- Average the Current Overall and Partner/Opponent gain estimates into one score.
- Add gain values from overlapping Improvement Opportunity rows together.
- Assume the lowest-rated skill, largest court-relative gap, or largest negative Key Driver is automatically the best Development Priority.
Why Trusted Pickleball Analytics Matter for Smart Courts
The long-term value of smart-court systems depends partly on whether players trust the analytics they receive. Players may tolerate imperfect highlights, missed clips, or occasional tracking problems — they are often much less tolerant of a rating that feels wrong. Analytics systems therefore become part of the platform’s trust infrastructure: players want believable explanations, meaningful performance tracking, trustworthy ratings, understandable insights, and visible improvement over time.
Video Collection and Analytics Modeling Are Different Problems
Video platforms solve difficult engineering challenges — capture, computer vision, shot detection, court tracking, streaming, workflow, user experience. Turning those events into trustworthy performance analytics introduces a different set of problems: weighting shot impact, handling teammate interactions, balancing game phases, measuring level of play, stabilizing ratings, managing noisy data, estimating reliability, and maintaining outcome alignment. These are sports-analytics problems rather than purely computer-vision problems.
Why Platforms May Partner Rather Than Build Everything Internally
Converting shot data into ratings can appear straightforward at first glance; in practice, producing analytics that consistently feel credible is difficult. Platforms that introduce ratings inherit player disputes, trust-management issues, volatility concerns, sandbagging concerns, support complexity, and pressure to explain results. The analytical layer can become one of the most sensitive aspects of the customer experience — PEWPEW was designed to provide that specialized analytical layer while allowing video and club platforms to focus on their own strengths.
How PEWPEW Thinks About Noise, Variance, and Data Quality
Outcome-based analytics inevitably contains noise — net cords, balls barely touching lines, camera obstruction, missed detections, incorrect shot attribution, player overlap, incomplete point tracking. These are legitimate concerns, and PEWPEW does not assume every observed event is perfect.
Not Every Form of Variance Should Be Corrected Away
Some apparent randomness contains genuine skill — targeting close to lines involves risk, aggressive shots create pressure, defensive tolerance changes the value of attacks, and difficult decisions can create opponent errors. Over-correcting every unusual result as “luck” can remove real competitive signal. PEWPEW’s general philosophy:
Correct clear measurement problems where possible, but avoid eliminating competitive variance simply because it is difficult to model.
Heuristic Models Contain Noise Too
Outcome-based noise is easy to see; heuristic noise is often less visible. A heuristic system must decide what a technically correct shot looks like and how much each mechanic, movement, positioning factor, or tactical characteristic should be weighted — those assumptions also contain uncertainty, often with no direct competitive outcome against which to evaluate the weighting. PEWPEW prefers to anchor performance analysis to observed competitive outcomes while acknowledging that no modeling framework is perfectly noise-free.
Where PEWPEW Is Still Limited
No performance-measurement system is complete, and it is worth being direct about where PEWPEW’s current limitations sit — both because transparency matters and because those limitations help define where ongoing development should focus.
- Granular subratings need volume. Highly specific phase and shot-type ratings can be based on relatively few player observations. PEWPEW therefore treats estimate reliability separately from the estimate itself; niche subratings should be interpreted more cautiously until sufficient observations accumulate.
- Single-camera attribution risk. Single-camera environments are more prone to obstruction, missed events, and shot-attribution errors than multi-camera setups, particularly in crowded kitchen exchanges. PEWPEW’s data-quality processes reduce but do not eliminate this risk.
- Doubles attribution is inherently imperfect. Estimating how much of a rally’s value came from the setup player versus the finisher is a genuinely difficult attribution problem. PEWPEW’s approach is designed to be more informative than simple winner/error counts, but it remains a modeled estimate rather than a direct measurement of intent or decision-making.
- Calibration is not out-of-sample validation. The calibration check described above shows that PEWPEW’s probability scale is internally coherent with the data used to build it. It is a different — and narrower — claim than demonstrating predictive accuracy on an unseen dataset, and should not be interpreted as one. It also isn’t perfect: the 85–90% bin’s larger-than-expected gap, despite a healthy sample size, is a live area of investigation rather than a solved problem.
- DUPR correlation is a benchmark, not a target. Because PEWPEW deliberately does not optimize purely toward matching DUPR, its ratings and DUPR will not always agree. Some disagreement is expected by design and is not automatically evidence of an error in either system.
Is PEWPEW Ready for Real-World Deployment?
PEWPEW is not merely a theoretical framework. The system has been developed and tested across thousands of pickleball games and large-scale shot-level rally data, spanning recreational and competitive play and imperfect real-world video feeds, including single-camera environments. The system was built around practical deployment constraints rather than idealized laboratory data, including obstruction, overlapping players, ambiguous kitchen exchanges, incomplete visibility, noisy event feeds, shot-attribution errors, and varying levels of competition.
Unified Rating Calibration Across Contexts
Different game phases naturally produce different distributions — some situations create larger leverage swings, some provide easier offensive opportunities, some contain more volatility, and some generate more terminal outcomes. Without calibration, certain game phases can appear artificially stronger or weaker. PEWPEW therefore calibrates overall, phase, subphase, and shot-type ratings onto a common broad framework, allowing more meaningful comparisons between different parts of a player’s game.
Reliability Matters
PEWPEW distinguishes rating level from rating reliability. A granular rating based on a small number of observations should not be treated as equivalent to one based on hundreds of observations. As a general statistical matter, performance estimates become more stable as relevant observations accumulate — this matters particularly for niche shot types, uncommon game phases, and highly specific subratings. PEWPEW is designed to communicate actionable information without creating false precision.
Built for Production Environments
The PEWPEW analytical pipeline is designed for rapid processing, scalable reporting, large-volume ingestion, smart-court integrations, consumer applications, and longitudinal player tracking. The objective was never simply to build an interesting analytical model — it was to build one capable of functioning in real pickleball ecosystems.
Glossary
- Modeled rally-win probability — PEWPEW’s estimate of the probability that a team wins the current rally, conditional on the competitive state represented by the model.
- Rally-win probability — shorthand for modeled rally-win probability when the context is clear.
- Pre-shot rally-win probability — the modeled probability immediately before a shot.
- Post-shot rally-win probability — the modeled probability immediately after a shot.
- Shot Impact — post-shot rally-win probability minus pre-shot rally-win probability.
- PEWPEWS — PEWPEW shot-value points accumulated across a set of shots.
- PEWPEWS/Shot — PEWPEWS normalized by shot volume; a core per-shot performance measure.
- Overall PEWPEW Rating — a calibrated summary measure of a player’s observed competitive performance.
- Current Overall Rating — the player’s Overall PEWPEW Rating for the analyzed sample; the primary benchmark for identifying internal development gaps.
- Shot Quality — the value-creation component of PEWPEW performance.
- Accuracy — the consistency and mistake-avoidance component of PEWPEW performance.
- Expected Match Win % — a descriptive translation of observed rally-winning performance into the match-winning rate that PEWPEW associates with that level of rally performance; it is not a forecast of a future rematch.
- Key Driver — an estimate of how much a broad game area contributed to the observed match result.
- Personal Performance Gap — an area where the player’s contextual PEWPEW Rating is below the player’s Current Overall Rating.
- Partner+Opponent Composite — pooled performance from the other players on the court — partner(s) plus opponents — in the same analytical context.
- Partner/Opponent Composite Rating — the contextual PEWPEW Rating associated with that pooled partner + opponent performance when reported.
- Court-Relative Weakness — an area where the player performs below the Partner+Opponent Composite in the same context.
- Improvement Opportunity — an independent estimate of what improving one specific area to either the Current Overall Rating benchmark or the Partner+Opponent Composite benchmark would be worth while the rest of the observed performance remains unchanged.
- Rally % Gain If Level With Current Overall Rating — estimated increase in Rally Win % if the area rose to the player’s Current Overall Rating level.
- Match % Gain If Level With Current Overall Rating — corresponding estimated increase in Expected Match Win %.
- Overall Rating Gain If Level With Current Overall Rating — estimated increase in Overall PEWPEW Rating; the primary development-ranking signal.
- Rally % Gain If Level With Partner/Opponents — estimated increase in Rally Win % if the area matched the Partner+Opponent Composite.
- Match % Gain If Level With Partner/Opponents — corresponding estimated increase in Expected Match Win %.
- Overall Rating Gain If Level With Partner/Opponents — estimated increase in Overall PEWPEW Rating if the area matched the Partner+Opponent Composite.
- Contextual subrating — a performance estimate restricted to a defined game phase, shot type, stroke, side, or other situational context.
- Reliability — the amount of confidence supported by the available sample; reliability generally increases as relevant observations accumulate.
- Kitchen — the non-volley zone, the 7-foot area on each side of the net where players cannot hit the ball out of the air.
- Third-shot drop — a soft, arcing shot hit by the serving team on the third shot of a rally, intended to land in the kitchen and neutralize the returners’ positional advantage.
- Third-shot drive — a faster, flatter alternative to the drop, hit with pace on the third shot.
- Transition / transition zone — the area between the baseline and the kitchen line; also refers to a team’s movement from the baseline up to the kitchen line after serving or returning.
- Reset — a soft, controlled shot used to neutralize a fast or aggressive ball and slow the rally back down.
- Speedup — an abrupt increase in pace during a soft-game exchange, intended to catch an opponent off guard.
- Dink — a soft shot hit from the kitchen line, typically arcing just over the net into the opponent’s kitchen.
- Counter — a shot hit in response to an opponent’s speedup or attack, typically redirecting pace rather than absorbing it.
Frequently Asked Questions
What is an Improvement Opportunity?
An Improvement Opportunity estimates what would change if the player’s performance in a specific area improved to one of two benchmarks: the player’s Current Overall Rating level or the Partner+Opponent Composite in the same context. PEWPEW expresses the estimated gain in Rally Win %, Expected Match Win %, and Overall PEWPEW Rating. Each opportunity is evaluated independently, and overlapping opportunity values should not be added together.
Which Improvement Opportunity benchmark is primary?
The Current Overall Rating benchmark is primary for development prioritization. It asks what a player would gain by bringing a lagging part of the game up to the level the player already demonstrates overall. The Partner+Opponent Composite is a secondary competitive benchmark showing whether that same area is also below the surrounding court.
What if an area is below my Overall Rating but already better than the court?
It can still be an important Improvement Opportunity. In that case, Current Overall gain fields may be populated while Partner/Opponent gain fields are blank. The area is holding back the player’s own level even though the player already matches or exceeds the surrounding court.
What if I am above my Overall Rating in an area but below the court?
That is a Court-Relative Weakness but not a Personal Performance Gap. It can be useful competitive context, especially on a strong court, but PEWPEW does not automatically prioritize it above higher-value areas that are below the player’s own Current Overall Rating.
Why are some Improvement Opportunity gain fields blank?
When the relevant benchmark data is available, a blank means there is no positive gain to show because the player already meets or exceeds that benchmark. If the benchmark itself is unavailable, a blank should not be interpreted as proof that the player exceeds it.
Should the two Improvement Opportunity benchmarks be averaged?
No. They answer different questions. Current Overall Rating measures the value of leveling up the player’s own game; Partner+Opponent Composite measures the value of catching up to the surrounding court. They should remain separate.
Does PEWPEW replace coaching?
No. PEWPEW is primarily a measurement and performance-tracking system. Coaches, players, and AI systems can use those measurements to inform development.
Why not just count winners and errors?
Because many of the most important shots occur before the final winner or error. Setup shots, pressure shots, resets, positional leverage, and teammate interactions can determine the rally long before the final ball.
Is PEWPEW a predictive model?
The underlying rally-win framework contains predictive estimates, but PEWPEW uses those estimates primarily for descriptive and diagnostic analysis of games that have already been played. Simply put: PEWPEW uses prediction as a measurement tool and uses those measurements to explain performance.
Why not simply train a video model to reproduce DUPR?
Because DUPR is an estimate of competitive strength, not literal ground truth. Optimizing entirely toward DUPR risks reproducing both DUPR’s valuable competitive signal and the uncertainty, player-pool effects, sample limitations, and systematic effects embedded in the existing rating network. PEWPEW uses DUPR as an important benchmark rather than defining model correctness solely by DUPR correlation.
Why does PEWPEW account for the overall level of play?
Because performing best on a particular court and performing at an elite absolute level are different concepts. PEWPEW attempts to preserve relative performance within the match while also calibrating for the broader level of play represented by that game.
Can AI understand pickleball without structured analytics?
AI can describe pickleball and provide general coaching advice, but reliable individualized explanation is much harder without structured performance data. PEWPEW provides the analytical layer that AI can interpret.
The Long-Term Vision for Pickleball Analytics
PEWPEW is built around a simple belief: players ultimately want trusted performance tracking.
Players do not wake up hoping for more statistics. They want a better understanding of their game. They want to know why they’re winning or losing, why they’re rated where they are, what’s holding them back, what to work on, whether that work is actually helping, and whether they’re improving.
Ratings remain important. DUPR has created an enormously valuable common currency for pickleball, and reaching a rating milestone can be a real and motivating objective for players.
The next generation of pickleball analytics should not ask players to stop caring about ratings. It should help connect those rating goals to the performance changes underneath them — first by identifying which parts of a player’s game lag their own current level, and then by showing whether those same areas also lag the surrounding court.
Instead of only telling a player where they stand, analytics should help answer:
- Why is this my rating?
- What is keeping me from the next level?
- Which part of my game is holding back my current level?
- Am I also behind the surrounding court in that area?
- Which weakness should I address first?
- What would improving it actually be worth in rallies, matches, and rating?
- Is the work I’m doing actually changing my performance?
Because PEWPEW is built from rally-winning value, it can connect those questions across the outcomes players commonly care about:
winning more rallies → winning more matches → reaching a higher measured performance level
That is the role PEWPEW is attempting to fill.
Players don’t need a better rating. They need ratings that help them get better.